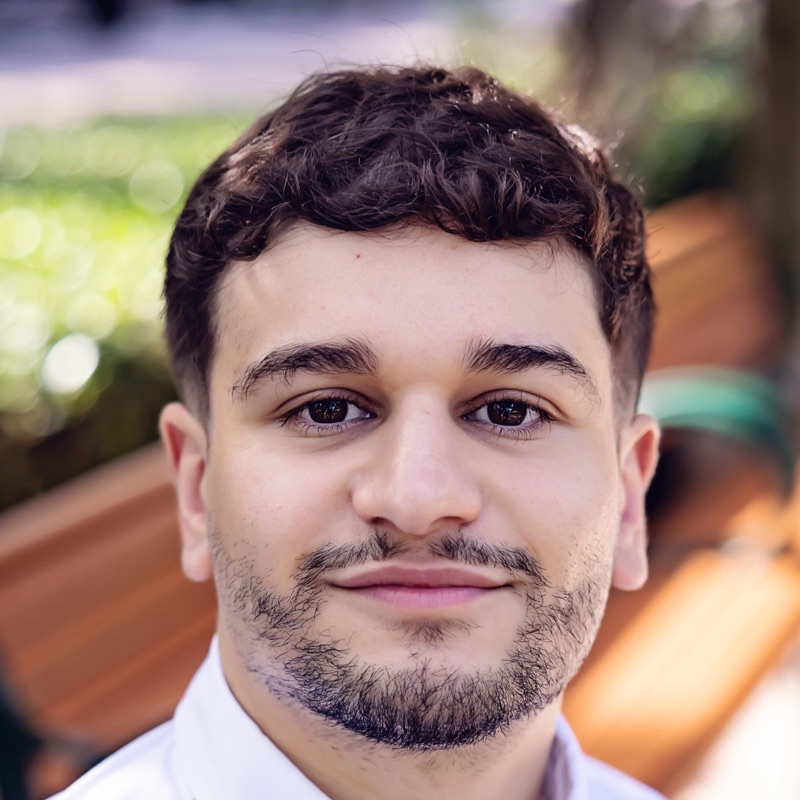
Portrait of Leo Benac

Leo Benac

Reinforcement Learning Researcher

PhD Candidate in Computer Science, Harvard University
Data to Actionable Knowledge Lab · advised by Finale Doshi-Velez

About

I’m a final-year PhD candidate in Computer Science at Harvard University (cross-registered at MIT), advised by Finale Doshi-Velez in the Data to Actionable Knowledge Lab. My research focuses on developing data-efficient reinforcement learning algorithms that extract insights from offline healthcare datasets to assist clinicians. I’m the inaugural recipient of the Yiming Zhang (Jump Trading) Graduate Fellowship in Artificial Intelligence, awarded for exceptional research potential in reinforcement learning. Through industry internships, I built an evaluation framework for AI agents at Waymo, forecast equity covariance matrices at Voloridge Investment Management, and applied RL to battery management systems (BMS) at Schneider Electric. Before Harvard, I earned an Honors degree in Statistics with a minor in Computer Science from Concordia University in Montreal, graduating with a 4.27/4.30 GPA (top 1%).

  • Reinforcement learning
  • Model-based RL
  • Inverse RL
  • Offline & safe RL
  • Multi-agent decision-making
  • Evaluation of AI agents
  • ML for healthcare

News

Research

Publications

Conference & journal papers

  1. RLC 2026

    Strategically-Linked Decisions in Long-Term Planning and Reinforcement Learning

    Alihan Hüyük, Jonas Raedler, Leo Benac, Finale Doshi-Velez

    Reinforcement Learning Journal, vol. 7 · Reinforcement Learning Conference (RLC) 2026

    Introduces strategic link scores, which measure how much an earlier action depends on a planned follow-up. They are used to explain black-box RL agents and to make decision-support recommendations more robust, across maze, chess, healthcare, traffic, and crisis-negotiation environments.

  2. AISTATS 2026

    Bayesian Inverse Transition Learning: Learning Dynamics from Near-Optimal Trajectories

    Leo Benac, Abhishek Sharma, Sonali Parbhoo, Finale Doshi-Velez

    International Conference on Artificial Intelligence and Statistics (AISTATS) · PMLR 300, 2026

    Learns environment dynamics from offline, near-optimal expert trajectories by turning the expert’s choices into constraints on a Bayesian posterior. This improves downstream decisions in synthetic tasks and in ICU management of hypotension.

  3. AISTATS 2025

    Decision-Point Guided Safe Policy Improvement

    Abhishek Sharma, Leo Benac, Sonali Parbhoo, Finale Doshi-Velez

    International Conference on Artificial Intelligence and Statistics (AISTATS) · PMLR 258, 2025

    Decision Points RL (DPRL) improves on a behavior policy only at frequently visited state–action pairs. Its safety guarantees depend on those visit counts rather than on the size of the state–action space, and it improves both safety and performance on synthetic and real-world tasks.

  4. AMIA 2024

    Pruning the Path to Optimal Care: Identifying Systematically Suboptimal Medical Decision-Making with Inverse Reinforcement Learning

    Inko Bovenzi*, Adi Carmel*, Michael Hu*, Rebecca Hurwitz*, Fiona McBride*, Leo Benac, José Roberto Tello Ayala, Finale Doshi-Velez

    AMIA Annual Symposium Proceedings, vol. 2024, pp. 202–211 · *equal contribution

    A two-stage inverse RL approach that recovers clinical priorities by pruning ICU trajectories that deviate from clinician consensus. The benefit of pruning varies across diseases and demographic groups.

Preprints

  1. Preprint 2026

    Quantifying Potential Observation Missingness in Inverse Reinforcement Learning

    Leo Benac, Abhishek Sharma, Alihan Hüyük, Finale Doshi-Velez

    arXiv:2605.12831

    Recorded decision data, such as ICU treatment records, often lacks information the decision-maker actually saw, which can make good decisions look suboptimal to inverse RL. This work estimates how much may be missing by finding the smallest observation changes under which the expert’s actions look optimal.

  2. Preprint 2026

    A Benchmark for Multi-Party Negotiation Games from Real Negotiation Data

    Leo Benac*, Jonas Raedler*, Zilin Ma, Finale Doshi-Velez

    arXiv:2603.14066 · *equal contribution

    A benchmark for multi-party negotiations in which agreement forms through a series of binding, partial commitments. It combines a configurable game generator, game instances grounded in a real climate-negotiation exercise, and baseline solvers. No single solver wins in every regime.

  3. Preprint 2021

    Risk-Averse Non-Stationary Multi-Armed Bandits

    Leo Benac, Frédéric Godin

    arXiv:2109.13977 · undergraduate research, Concordia University

    Two estimators of conditional value-at-risk (CVaR) for bandits whose losses drift over time. They plug into standard policies such as ε-greedy and, in simulations, outperform approaches that ignore non-stationarity.

Workshop papers

  1. ICML 2023 Workshop

    Bayesian Inverse Transition Learning for Offline Settings

    Leo Benac, Sonali Parbhoo, Finale Doshi-Velez

    Interactive Learning with Implicit Human Feedback Workshop, ICML 2023 · arXiv:2308.05075

    The precursor to BITL: a gradient-free, constraint-based posterior over transition dynamics learned from expert data, which yields high-performing policies with much lower variance across datasets.

  2. ICML 2023 Workshop

    Inverse Transition Learning for Characterizing Near-Optimal Dynamics in Offline Reinforcement Learning

    Leo Benac, Sonali Parbhoo, Finale Doshi-Velez

    “Could It Have Been Different?” Counterfactuals in Minds and Machines Workshop, ICML 2023

Experience

Industry

  1. May – Sep 2026

    Data Scientist Intern · Waymo

    Mountain View, CA

    • Implemented from scratch and deployed an end-to-end evaluation framework for Waymo’s AI agents.
    • Built synthetic data generation pipelines and curated golden datasets; implemented LLM-as-a-judge metrics, regression tests, and online evaluation.
    • Enabled engineers to systematically identify agent failure modes and target improvements.
  2. May – Aug 2025

    Quantitative Researcher Intern · Voloridge Investment Management

    Jupiter, FL

    • Built factor models of volatility and correlation to forecast the daily covariance matrix of asset returns.
    • Analyzed 30+ years of US equity data (8,000+ stocks), detecting vendor errors and uncovering trends; gave 5 research presentations to portfolio managers.
  3. Jun – Dec 2024

    AI Research Scientist Intern · Schneider Electric

    Andover, MA

    • Built an OpenAI Gym–compatible simulator of battery cell charge/discharge cycles.
    • Designed RL agents (PPO, DQN, SAC) for battery cell balancing that outperformed baselines by 15%.
    • Developed an RL agent to optimize battery energy storage within a microgrid for charging efficiency and cost.

Undergraduate research

  1. May – Sep 2021

    Research Assistant in Reinforcement Learning · Concordia University

    Montreal, QC · selected among 60+ undergraduate students

    • Developed risk-averse multi-armed bandit algorithms for non-stationary settings, outperforming baselines by 10% (paper).
  2. May – Sep 2020

    Research Assistant in Machine Learning · Concordia University

    Montreal, QC · selected among 60+ undergraduate students

    • Implemented the Viterbi algorithm for part-of-speech tagging in NLP.

Education

  1. 2022 – May 2027
    (expected)

    PhD in Computer Science · Harvard University

    Cambridge, MA · cross-registered at MIT

    Research focus: reinforcement learning. Advisor: Finale Doshi-Velez. Yiming Zhang (Jump Trading) Graduate Fellow.

  2. 2018 – 2022

    Bachelor of Honors in Statistics, minor in Computer Science · Concordia University

    Montreal, QC

    GPA 4.27/4.30 (top 1%). Eric O’Connor Mathematics Medal for the highest GPA among graduating Mathematics students.

Teaching & Talks

Teaching

  1. Spring 2026

    Teaching Fellow, Ethics in Data Science · Harvard

    Required course for Harvard’s Data Science master’s program. Co-organized course content, lectures, and the course website; facilitated in-class discussions and graded assignments.

  2. Fall 2023

    Teaching Fellow, Inverse Reinforcement Learning · Harvard

    Co-organized course content and lectures, held weekly office hours, and supervised 50+ students on research projects.

Invited talks

  • 2026 Jump Trading AI Symposium, New York City
  • Center for Human-Driven AI Research and Methods (CHARM), Harvard
  • 2023 RL at Harvard Workshop
  • 2023 Interactive Learning with Implicit Human Feedback Workshop, ICML
  • 2023 “Could It Have Been Different?” Counterfactuals in Minds and Machines Workshop, ICML

Honors

  • 2026 Yiming Zhang (Jump Trading) Graduate Fellowship in Artificial Intelligence, inaugural recipient; awarded for exceptional research potential in reinforcement learning; covers tuition and stipend for up to two years
  • 2022 Eric O’Connor Mathematics Medal, awarded to the graduating Mathematics student with the highest GPA (Concordia)
  • 2022 MASSA Grant ($500), for outstanding students in Mathematics & Statistics
  • 2022 Arts & Science Scholar, top 1% of students in Mathematics & Statistics
  • 2021 Concordia Undergraduate Student Research Award ($8,000)
  • 2021 Arts & Science Scholar, top 1% of students in Mathematics & Statistics
  • 2020 Concordia Undergraduate Student Research Award ($5,760)
  • 2020 Arts & Science Scholar, top 1% of students in Mathematics & Statistics
  • IVADO Fin-ML CREATE Undergraduate Research Scholarship ($6,000), for high academic performance
  • T.S. Dwivedi S.N. Mishra Statistics Scholarship ($500), for an outstanding Statistics student
  • Campaign for the New Millennium Scholarship ($400), Faculty of Arts and Science

Beyond Research

Basketball has been a constant for me: I played in high school and college, reaching the Arizona state championship in 2015. I’m now a student manager and practice player for Harvard’s Division I women’s basketball team, the 2025 Ivy League champions. I’m also interested in real estate investing.

Contact

The best way to reach me is by email at . I’m based in Cambridge, MA, and I’m happy to talk about research, collaborations, or roles starting in 2027.